Own project · AI research agent · 2026
Theos
An AI researcher that runs 24/7 and upgrades itself
- Role
- Solo build
- When
- Sep 30, 2026 – now
- Built with
- Python, Claude, OpenClaw
- Status
- Live 24/7
- 519
- commits in 15 days
- 152
- changes it proposed itself
- 17–3
- wins vs plain AI search
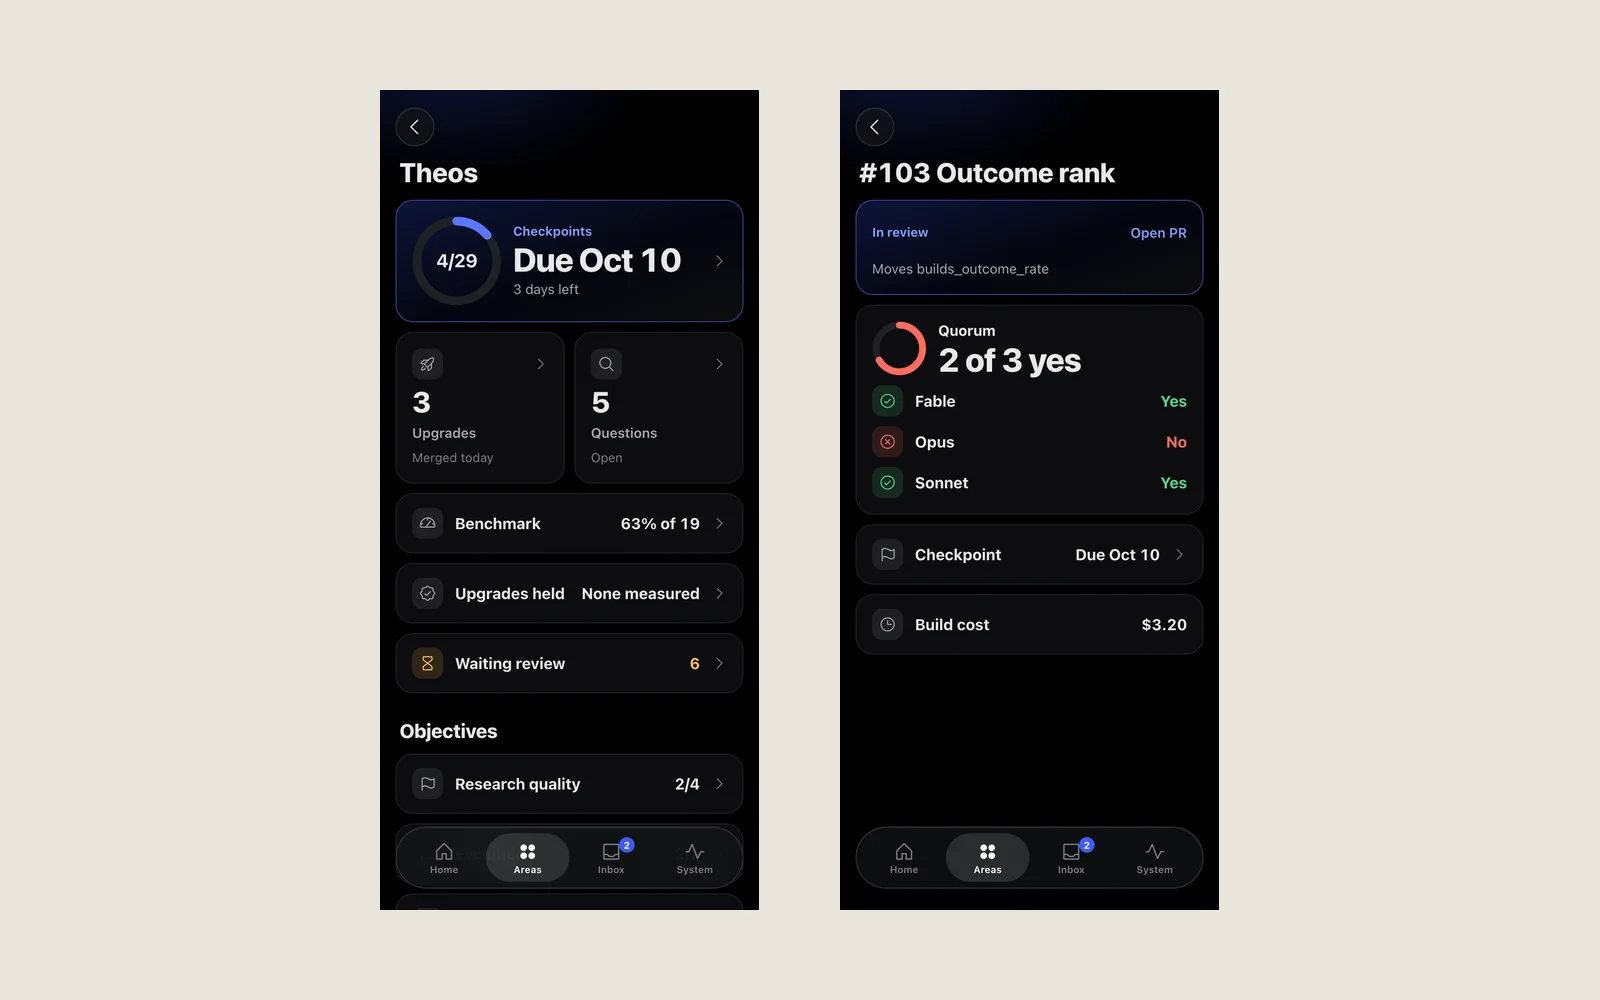
The before
AI models stop learning at a cutoff. I kept losing hours checking what was actually current.
What I built
A cited briefing every morning.
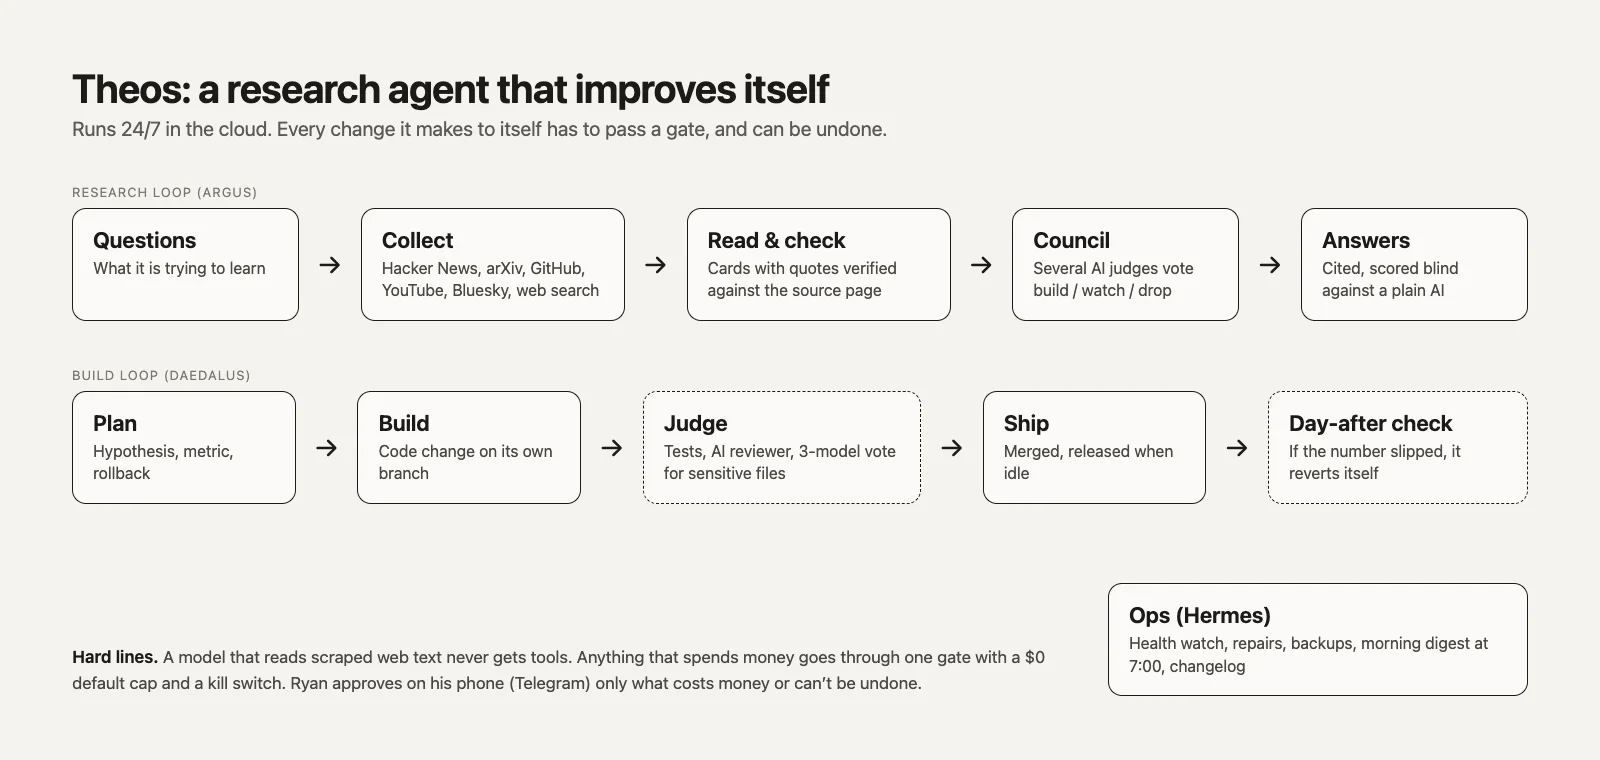
Features
01Reads the field daily
Papers, GitHub, YouTube and more, and every quote is checked against the source.
02A council decides
AI judges vote on each idea, and big calls need three models to agree.
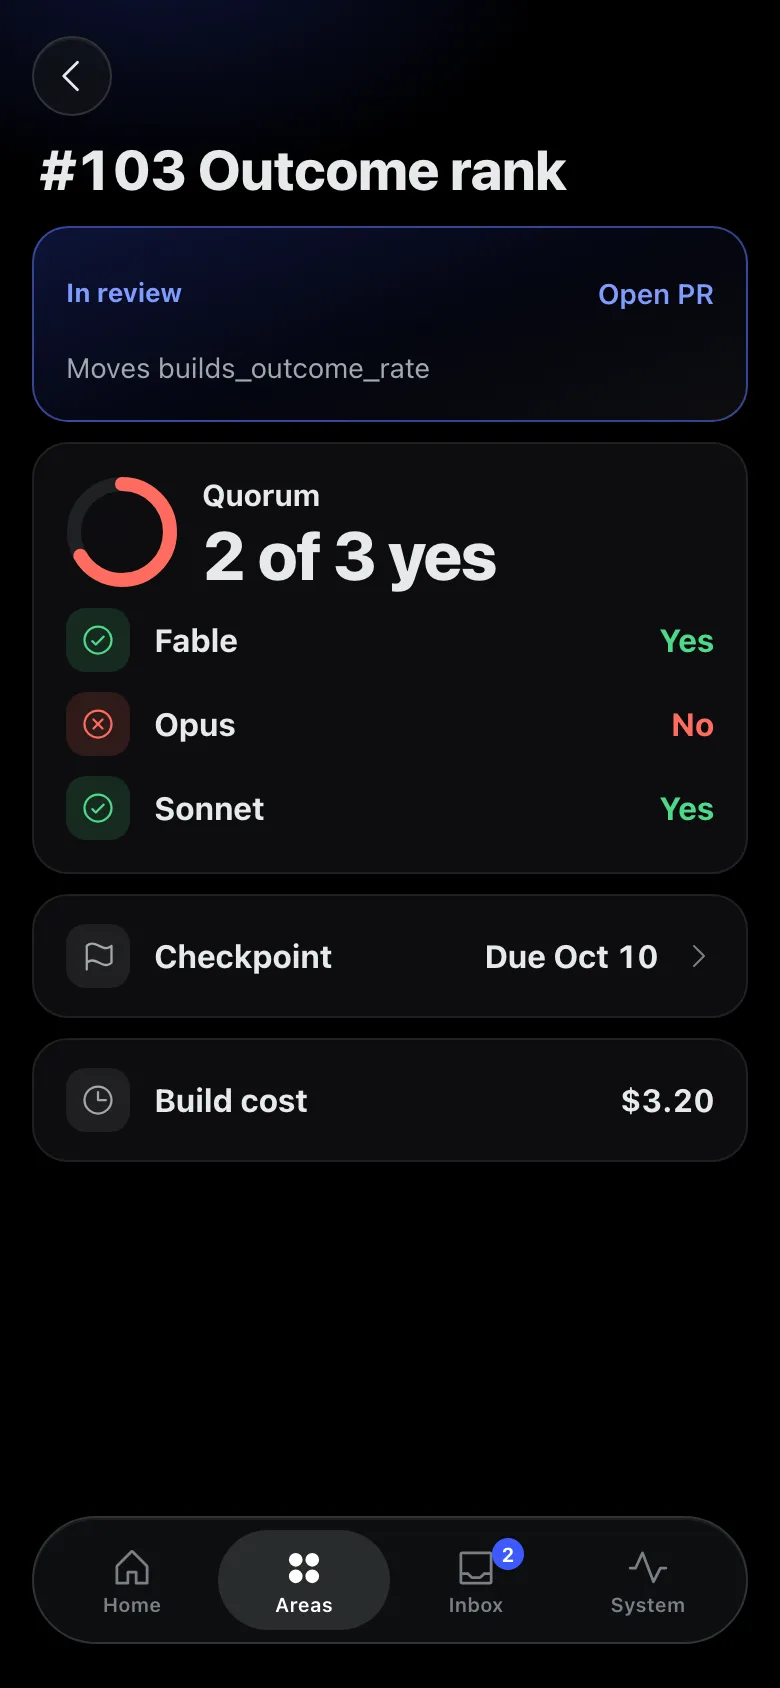
03It upgrades itself
It writes and ships its own changes, and reverts them if the number slips.
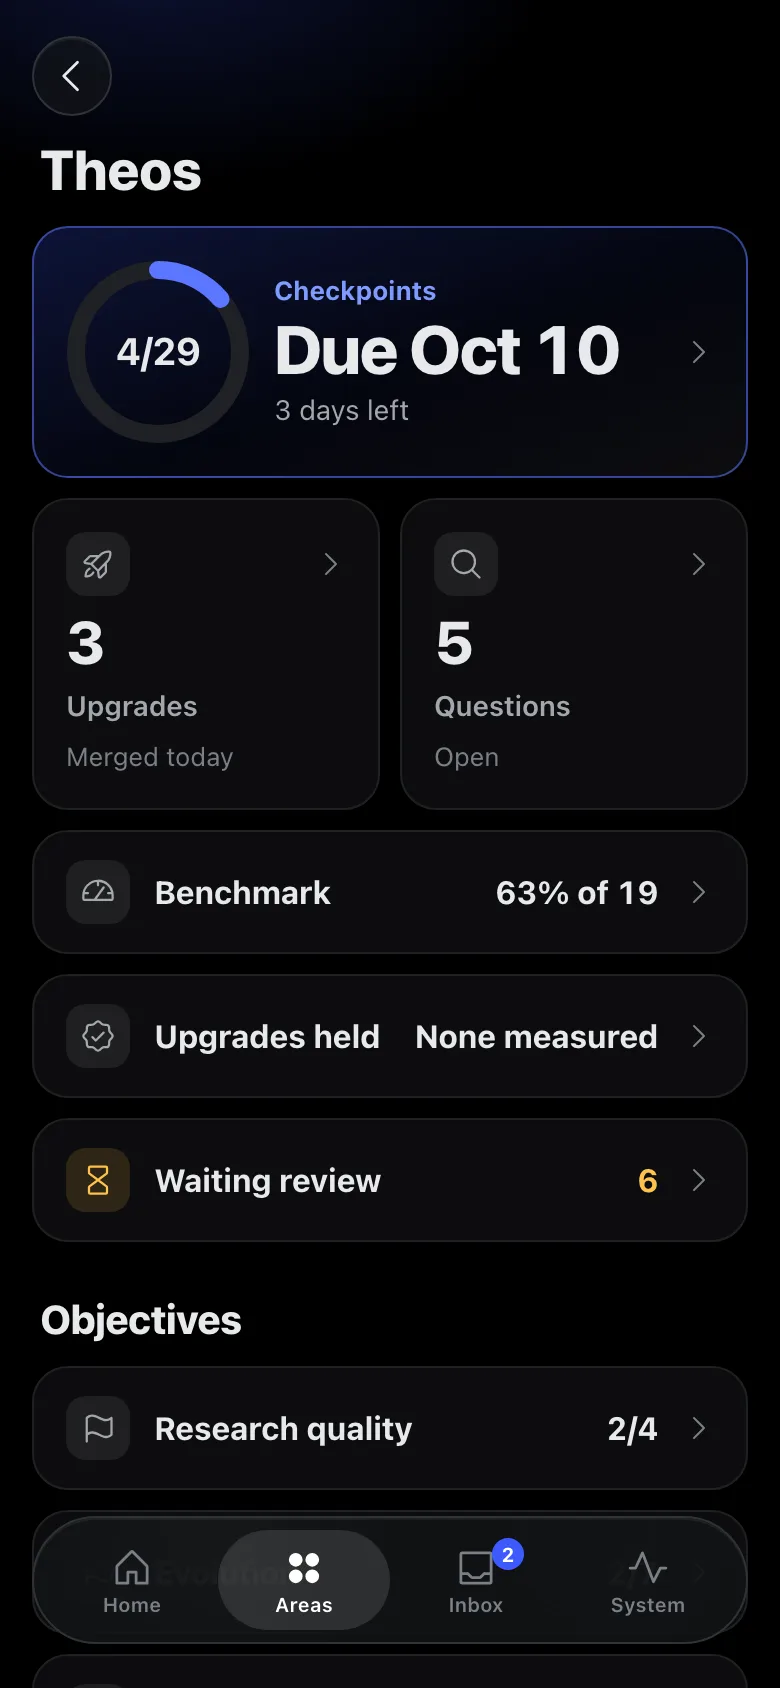
04Hard rules
A model that reads the web never gets tools, and spending is capped at $0.
| Level | What it means |
|---|---|
| Auto | Does it and logs it |
| Quorum | Three AI models must agree |
| Approve | I tap yes on my phone |
Why it matters
Source: Blind AI-judged matchups vs plain web search. Oct 13: 17 of 26 (6 ties, 3 losses).
Honest part: none of its first 20 self-upgrades helped.
How it works
- Standing questions
- Collect + verify
- AI council
- Morning briefing
- Self-upgrade
Three budgeted workers research, build and keep things healthy.
Technical details +
Hard problems
- Building isn't improving. Changes now need a number and a next-day check.
- A test with live keys closed every build for days. Fixed.
- An outside runtime hijacked its Telegram bot for 70 minutes.
Stack
- Python 3.12 + FastAPI
- Claude, zero tools per call
- OpenClaw as the scheduler
- SQLite on Railway
What I learned
- —If a plain tool beats yours, adopt it. That one became its first collector.
- —An AI that builds isn't an AI that improves. Without a metric, it's busy.
Thinking of letting AI run on its own? I'll show you where mine broke.